


Flexor just ranked #1 on the EnterpriseRAG benchmark, with an overall score of 91.48.
The EnterpriseRAG benchmark tests whether AI can answer real questions about a company’s business data, i.e. the messy internal data that’s most difficult to utilize: documents, Slack threads, emails, notes and call transcripts.
Every system is scored on answer correctness, answer completeness and document recall. Flexor scored 93, 94.37 and 93.62 respectively, putting it at the number one spot overall.
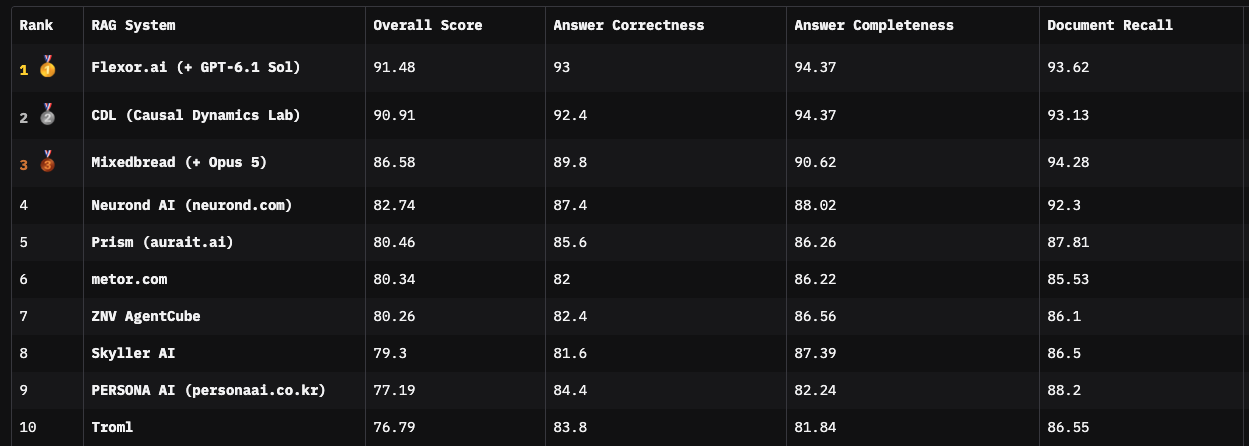
See the full EnterpriseRAG leaderboard on Hugging Face
The harder the question, the bigger the lead
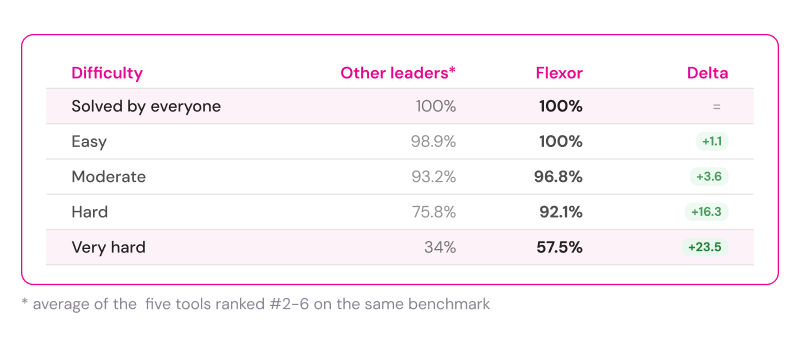
The overall score only tells part of the story. We split the benchmark’s 500 questions by how many systems managed to solve them, and a clear pattern appears: the harder the question, the wider Flexor’s lead.
Easy questions, like “How many days off do we get?”, are answered correctly by almost every system. Harder ones, like “Find every internal thread (email, Slack and meeting notes) about a specific bug,” are a different story, and most systems can’t answer them.
On hard questions, Flexor answers 92.1% correctly, vs. an average of 75.8% for the systems ranked #2 to #6, a 16.3-point lead. On very hard questions, the gap grows to 23.5 points (57.5% vs. 34%).
And real enterprise work is mostly hard questions: “What date did our security lead commit to completing the security review?” or “Who committed to delivering the demo for the upcoming customer renewal review, and what exactly was it supposed to showcase?” The answers are scattered across documents and sources that contradict each other, and that’s where most enterprise AI falls short.
The difference isn’t a bigger model. It’s what happens to the data before the model ever sees a question. Flexor ACE parses, extracts and indexes every source up front, automatically learns your domain’s terminology and specific company lingo right from the data, and runs the most robust retrieval strategies. The result is nearly perfect recall, while using 60–98% fewer tokens.
Sovereign AI: SOTA-level results from a self-hosted OSS model
There was a result we chose not to submit (since you can only submit one), and this result might be the most interesting one for organizations pursuing sovereign AI.
Alongside our run with GPT-6.1 Sol which brought us to the #1 place, we ran Flexor ACE with an open-source (OSS) model. It scored 83.28 overall. On the leaderboard, that would have placed fourth.
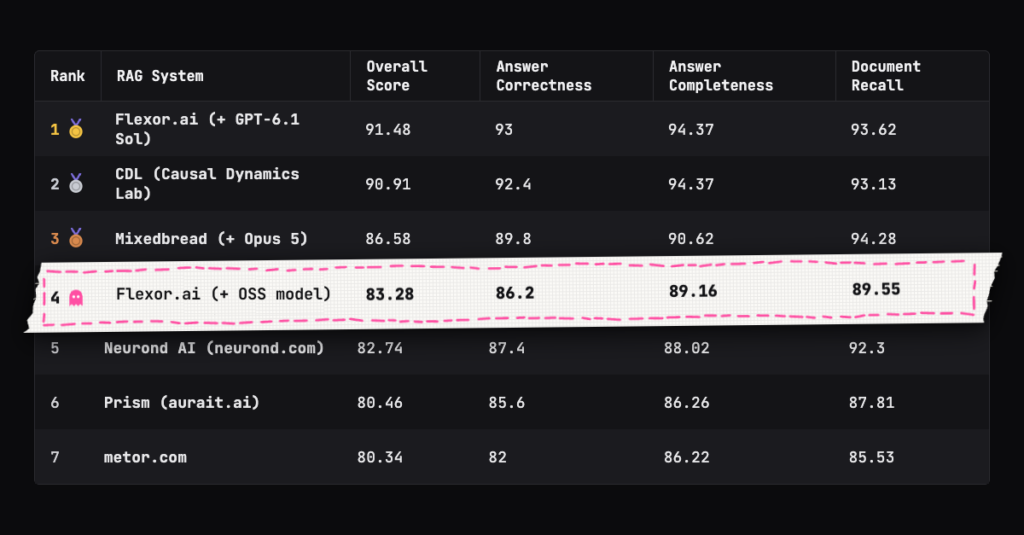
Yes, an OSS model, competing with the top proprietary ones, when fed the right context.
For enterprises that need to keep both their data and their models in-house, this opens up new possibilities. Open source models like Meta’s Llama can provide accurate results, while still keeping their original benefits of being extremely fast, cheap to run and with the option to be fully self-hosted. Combined with the right retrieval engine, you don’t have to trade sovereignty for performance.
The same preparation behind these results can run on your own data. Contact us and see how your hardest questions hold up.

