



Ask any team that has shipped an AI project inside a large company where the time went, and the answer is rarely “the model.” It went into finding the data, cleaning it, arguing about which version was right, and rebuilding the same pipeline for the third time.
AI data preparation is the work of turning raw enterprise data into something an AI system can use reliably. It sounds like plumbing. In practice it decides whether a project ships, how much it costs, and whether people trust the answers. This article walks through what it involves, why enterprise data makes it hard, and what changes when you automate it.
Key takeaways
- Preparation is the first bottleneck, not the last. Teams usually plan for model work and get surprised by data work, which takes longer and repeats for every new use case.
- It is a chain of stages. Ingestion, parsing, cleaning, normalization, enrichment and structuring each fix a different problem, and skipping one shows up later as a wrong answer.
- Unstructured data is where it gets hard. Emails, PDFs, call transcripts and chats carry most of the business context and resist the tools built for tables.
- Automating it changes the economics. When preparation runs once and serves every project, teams spend their time on use cases instead of pipelines.
Why data preparation is the bottleneck enterprise AI hits first
Most AI projects start with a working demo. Someone exports a few hundred clean documents, connects a model, and gets impressive answers in a week. The plan for production assumes the hard part is done.
Then the project meets the real data. It lives in a dozen systems, in formats nobody chose on purpose, with duplicates, gaps and contradictions built up over years. Every one of those problems has to be solved before the AI can be trusted, and none of them were in the demo.
Three things make this stage slower and more expensive than teams expect:
- It is hidden in the estimate. Project plans budget for model selection, prompts and integration. Data work gets one line, then takes most of the timeline.
- It repeats. Each new use case starts its own extraction and cleanup, so the same documents get processed five different ways by five teams.
- It never finishes. Data changes daily. A pipeline that was right in March quietly drifts by June unless someone keeps it current.
We wrote about this pattern in does AI implementation feel like a struggle?: pilots stall not because the model is weak but because the data underneath it was never ready.
What AI data preparation involves in an enterprise context
It helps to think of preparation as a chain. Each stage fixes one kind of problem, and together they form the AI data pipeline that sits between your sources and your applications.
1. Ingestion
Connect to every source the use case needs: file shares, email, CRM, ticketing systems, call recordings, data warehouses. The goal is one consistent way in, not a custom script per system, and a record of where every item came from.
2. Parsing and extraction
Turn each format into usable text and structure. That means reading scanned PDFs, keeping tables intact, following the reading order of complex layouts, transcribing calls, and keeping an email linked to its attachments.
3. Cleaning
Data cleaning removes what gets in the way: boilerplate, signatures, legal footers, broken characters, and near-identical copies of the same document. Deduplication matters more than it sounds. Ten copies of one policy will crowd out the passage you actually need.
4. Normalization
Make the same thing look the same everywhere. Dates in one format, currencies in one form, and a customer who appears under five spellings resolved to one entity. This is the step that lets AI compare and combine information across sources.
5. Enrichment
Add the context the raw data does not carry: document type, owner, product line, region, time period, access rights, and the company’s own terminology. This is where data enrichment AI earns its keep, classifying and tagging content at a volume no team could label by hand.
6. Structuring and delivery
Shape the result for how it will be used: structured tables for analytics and process automation, and well-formed, searchable context for agents and retrieval. In practice this is a data transformation pipeline that writes prepared data back to the platform your teams already use.
Why enterprise data is harder to prepare than it looks
Each stage above is simple in principle. The difficulty comes from what enterprise data actually looks like.
- Too many formats. One process can span PDFs, spreadsheets, scanned forms, emails, chat threads and recordings. Every format needs different handling, and each handler is another thing to maintain.
- Inconsistency by default. Different teams, regions and acquired companies describe the same thing in different ways. Product names, customer names and status codes rarely match across systems.
- Duplicates and versions. Documents get copied, forwarded, edited and re-uploaded. Without deduplication and version awareness, the AI cannot tell the signed contract from the draft.
- Context that lives between documents. An email only makes sense with its attachment. A call only makes sense with the account it was about. Preparation has to keep those links, not just the text.
- Constant change. New tickets, emails and calls arrive every minute. Reprocessing everything on a schedule is slow and expensive; missing changes means stale answers.
This is why so much enterprise knowledge stays out of reach. As we put it in AI is moving fast. It just doesn’t know your business, the information exists. It just is not in a shape AI can use.
How automated data preparation changes what AI teams can do
Manual preparation does not scale because every step needs a person: writing a parser, fixing a mapping, reviewing a duplicate. Purpose-built automation removes that bottleneck in a few specific ways.
Prepare once, use everywhere
When preparation runs as shared infrastructure rather than inside each project, every team draws on the same cleaned and enriched data. New use cases start from prepared data instead of raw exports, and answers stay consistent across teams. We call this a data foundation, and our post on RAG for enterprise shows why retrieval depends on it.
Handle any type of unstructured data
Automation that only handles clean text leaves the hardest material behind. The value is in covering documents and conversations alike: contracts and invoices, but also emails, call transcripts and chat history.
Keep it current without reprocessing everything
Incremental processing detects what changed and handles only that. Data stays fresh, and compute costs track the rate of change rather than the size of the archive.
Serve agents and automation tasks from the same work
The same prepared data can feed dashboards and process automation for people, and context for AI agents. Teams that start with analytics and automation can move to agents without preparing the data again.
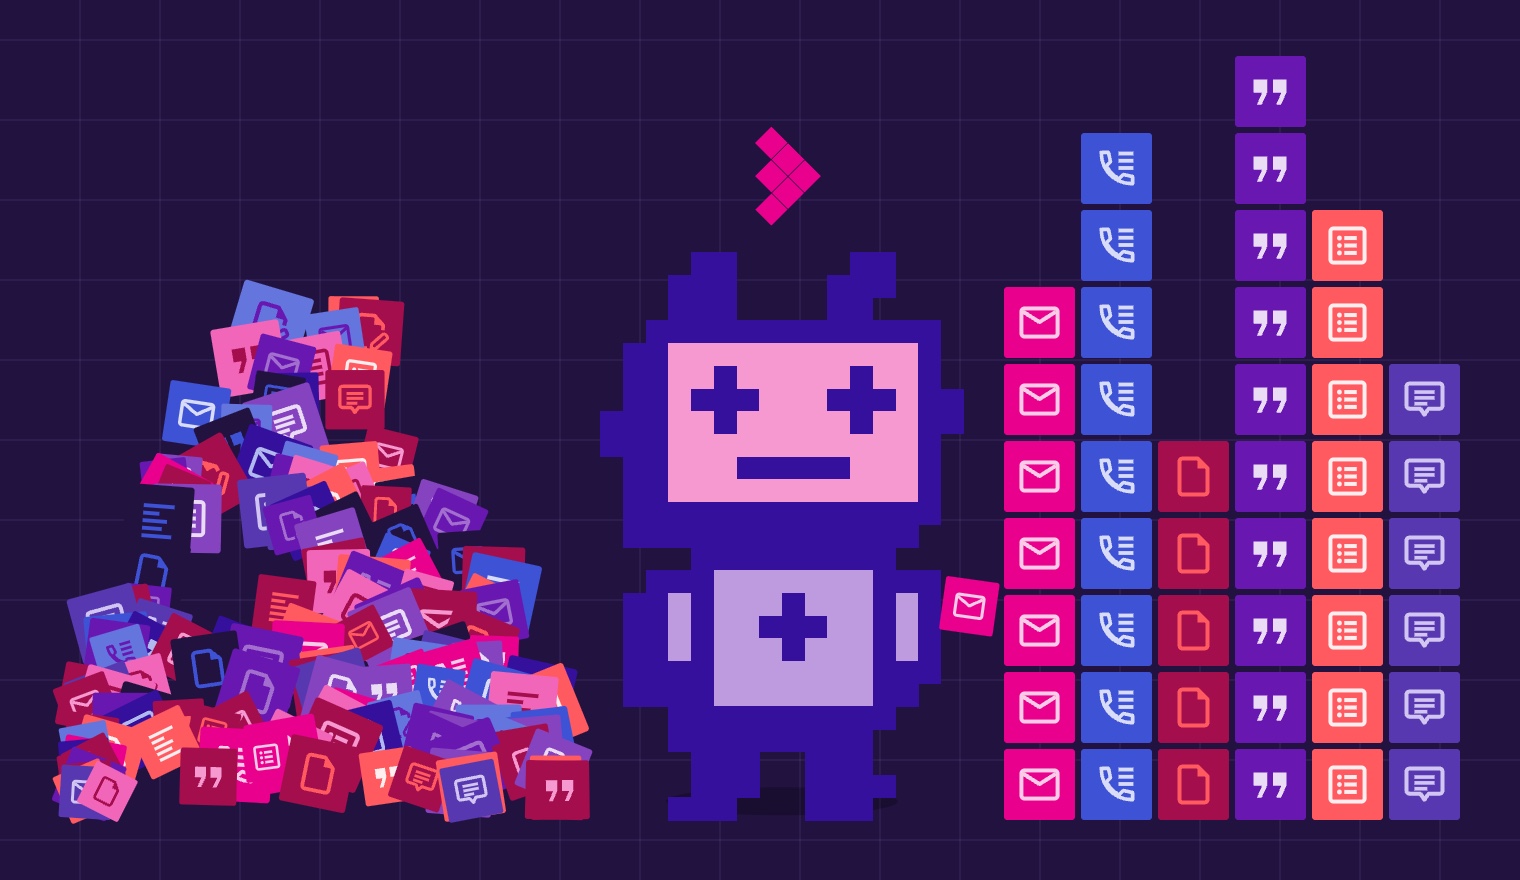
This is what Flexor ACE automates. It parses, extracts, cleans, normalizes and classifies any type of unstructured data, adds business context and domain terminology, and writes the result back to your data platform as Iceberg or Delta Lake tables. Change data capture means no document is processed twice, processing uses zero-data-retention models, and agents connect through a single MCP endpoint. Your team builds use cases instead of maintaining pipelines.
Curious what this looks like on your own data? Book a demo of Flexor ACE.
FAQs
What is the difference between data preparation and cleaning?
Cleaning is one step inside preparation. It removes errors, noise and duplicates. Preparation is the full chain that makes data usable for a specific purpose: ingesting it from sources, extracting text and structure, cleaning, normalizing formats and names, enriching it with metadata and business context, and delivering it in the shape an AI system or analytics tool needs. Clean data can still be unprepared if it lacks context or structure.
How long does data preparation for AI typically take?
It depends on the number of sources and how messy they are. A focused pilot on one clean source can be ready in days. A production use case spanning several systems and unstructured formats often takes months when done by hand, and the work repeats for each new use case. Automated, shared preparation shortens that to the time it takes to connect sources, because the cleaning and enrichment rules already exist.
Can data preparation be fully automated?
Most of it can. Ingestion, parsing, deduplication, normalization, classification and incremental updates are well suited to automation, and that is where most of the manual effort goes today. People still play a role in defining business terms, setting access rules and reviewing edge cases where the meaning is ambiguous. The aim is to move people from repetitive cleanup to the decisions only they can make.
What data formats does enterprise AI preparation handle?
Enterprise preparation has to cover structured data such as database tables and spreadsheets, semi-structured data such as JSON and logs, and unstructured data: PDFs, scanned documents, Word files, slides, emails with attachments, chat messages, support tickets and call recordings or transcripts. Unstructured formats are the hardest and the most valuable, because they hold much of the business context that structured systems leave out.
How does poor data preparation affect model accuracy?
A model can only reason over what it is given. Duplicates and outdated versions lead it to cite the wrong source. Missing metadata stops it from preferring recent or authoritative content. Inconsistent naming makes it miss relevant information entirely. The result looks like a model problem, with confident but wrong answers, yet better preparation fixes it more reliably than switching models or tuning prompts.